When the API Owns the State Machine Your Integration Tests Have to Follow It
Stateful simulators catch the broken flows that canned mocks miss.
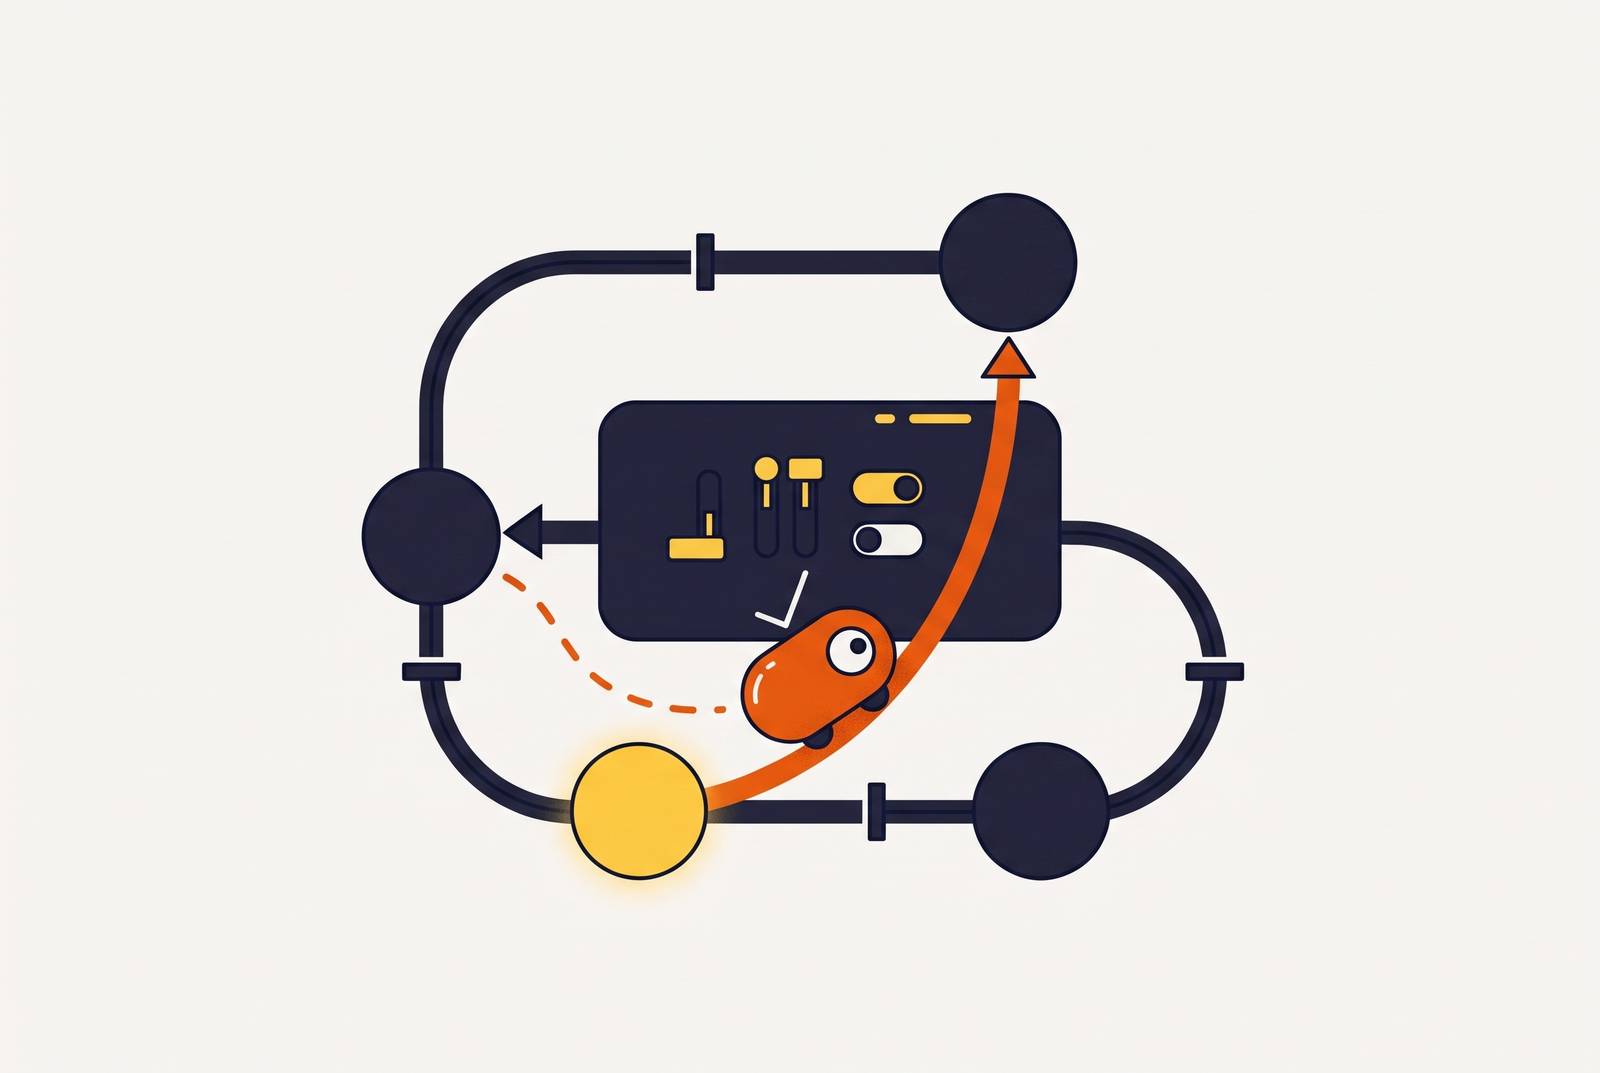
Integration testing against stateful APIs requires a simulator that remembers earlier calls, enforces the provider’s transition rules, and is continuously verified against the live API. Tests must run through whole flows, including failures and downstream webhooks, rather than accept canned responses that are independent of one another. This allows CI to test the integration without production access while preserving the constraints that make the real API work.
Why third-party APIs are state machines, not request-response services
A third-party API owns resources whose current state determines what a caller may do next. Earlier calls establish the conditions for later ones. A response therefore depends not just on the request’s shape, but on whether the referenced resource exists and whether the requested operation is allowed at that point.
Stripe’s payment intent lifecycle makes that dependency concrete. A payment intent begins in requires_payment_method and can reach succeeded after confirmation when capture_method is automatic, the default. With manual capture, confirmation instead leads to requires_capture, and capture must happen before the payment succeeds. Refunds are available after funds have been captured. Before capture, an authorized payment must be canceled.
The payment intent ID returned by creation must be used in subsequent operations, and the API rejects a reference to an ID it did not issue. Correct sequencing alone is not enough. The caller must perform the permitted operation on the resource that the earlier call actually created.
What it means for a test to be valid when the API has memory
A practical diagnostic is to create a resource, reference it in a subsequent operation, and read it back later in the flow. The read must reflect the earlier write. The same test environment must reject an invalid transition, such as refunding an uncaptured charge, with the documented error. When a state change produces a webhook, the test must also demonstrate that the correct downstream event fires.
These checks establish three distinct properties of an integration. Resource persistence proves that later calls operate on accumulated state. Transition enforcement proves that the test environment distinguishes permitted operations from forbidden ones. Webhook behavior proves that a change reaches the integration through the event path as well as the immediate response. Together, they test more than a collection of response shapes.
A successful read is evidence only if its result depends on the resource created earlier. Likewise, an error is evidence only if the resource’s current state makes the operation invalid. A suite that cannot distinguish those conditions is not exercising the provider’s state machine, even if every returned object conforms to the expected schema.
Why stateless mocks produce tests that pass and integrations that break
Consider a flow that posts a customer, posts a subscription referencing that customer, and then gets the subscription to assert that the customer is attached. A stateless mock can return consistent-looking JSON for every step. Nothing has to connect those responses internally. The subscription response can name the expected customer without requiring that the creation call established a customer at all.
On the real API, those calls exercise linked constraints. The customer must exist, the subscription must reference it, and the later read must return the relationship established by the write. With independent canned responses, the assertions instead confirm that the fixtures agree. Editing fixtures more carefully cannot close that gap in how the tests work. Tracking writes and using them to govern later responses requires stateful behavior.
Mocks remain useful for their intended purpose of unit-test isolation. A test can legitimately assert that a function calls the right URL with the expected headers or sends a body of the required shape. Those are meaningful checks of local behavior, but they do not establish that a multi-call integration works. Treating them as integration verification permits a passing suite immediately before a deployment encounters a constraint the fixtures never enforced.
What a stateful simulator actually does differently at each step of a flow
A stateful simulator stores the payment intent when the creation call succeeds and returns an ID for that stored resource. A later call uses that ID to address the same intent. The reference now has a real dependency. Reading the intent returns its accumulated state rather than a separately configured response that happens to look compatible with creation.
At confirmation, the simulator applies the transition rules for the selected capture method. Automatic capture can lead straight to succeeded, while manual capture needs a separate capture operation. A premature refund must fail. After capture, the simulator permits the refund according to the modeled rules, and state changes fire the corresponding webhook events. Each response follows from the resource’s history.
Storage, ID chaining, transition guards, and webhook delivery together give the API its memory. None is sufficient alone.
AWS Step Functions documentation describes a related way to test with its TestState API, added starting November 2025. It allows AWS service integrations to be mocked so state machine logic can be tested without calling actual services, including Map, Parallel, and Activity states. Although that capability addresses a different testing surface, it reflects the same need to exercise orchestration without invoking every live dependency.
How can stateful API tests run in CI without live credentials or rate limits?
A local stateful simulator can run as a dependency-free service in CI, without live provider credentials or exposure to provider rate limits. The tests still create resources and follow their transitions, but all those steps take place inside the simulated environment. Simulating stateful behavior locally avoids the setup and limits that otherwise make isolated response fixtures easier to use.
Exit code 0 means all workflows pass, and exit code 1 means a step failed. CI can therefore catch integration regressions before they reach staging without requiring a person to interpret each response. The test exercises the sequence, and the exit status gives the pipeline a machine-readable outcome.
Isolation is equally important for repeatability. Per-session state prevents one run’s resources from affecting another, avoiding the shared-state flakiness associated with vendor sandboxes that share state across API keys. Creating a test order in a live ERP or posting a test record to a live CRM changes the system under test. With a local simulation layer, routine CI runs can test those write-dependent flows without making those live changes.
Why simulator fidelity requires continuous verification against the live API
A simulator can keep state perfectly and still enforce the wrong rules. If its model reflects an older version of the provider’s behavior, a passing test proves compatibility with that older model. Statefulness does not prevent drift by itself. Fidelity must be maintained through continuous verification against the live API, rather than assumed from the simulator’s original construction.
An OpenAPI-based approach can tie transitions to responses and status codes already defined in the document. That grounding is useful only if the document remains current and is checked against actual provider behavior. A specification is not an independent guarantee of accuracy. A simulator generated from it at a single point in time can fall out of sync as the API evolves.
The relevant evidence includes the age of the underlying contract, OpenAPI examples that fail their own schemas, and operations with no provider verification run against them. Without that verification, production may be the first place a team discovers a newly required field, a changed enum value, or an altered transition. The simulator would then reproduce the same false confidence as a stateless mock, despite having a more capable architecture.
Fault injection as a required dimension of stateful integration testing
Successful transitions cover only part of an integration’s behavior. Endpoint-specific 401 responses, 429 rate limits, delayed webhooks, and duplicate or out-of-order deliveries change the conditions under which a flow must operate. Failure handling needs the same state context as success. An isolated error response cannot establish how the integration behaves after earlier operations have already changed a resource.
A stateful fault scenario can inject a 401 at a particular point in the flow and expose the simulator’s state at that moment. The test can then examine the integration’s handling of the failure and verify that the scenario resets to a known baseline afterward. The placement of the fault is essential. It sets which earlier operations have taken effect and which later operations can still go ahead.
Webhook faults belong in that same framework. Duplicate deliveries, out-of-order events, and stale replays are documented in production as well as being unusual inputs for a handler unit test. Exercising them against accumulated state tests whether event handling remains correct as delivery order diverges from the successful sequence. A simulator that supports only the happy path leaves this part of the integration untested, even when its normal transition model is accurate.
Stateful, verified simulators as the testing substrate for AI agents that call external APIs
AI agents that call external APIs face the same resource identities and transition guards as other software. Their natural-language output, however, can conceal a failed operation. Coherent text is not proof of execution. An agent may send malformed JSON to a payment API, choose the wrong endpoint, or misread a response while still producing a plausible account of the task.
AgentChaos, released in August 2026, injected faults into LLM API responses at runtime across five agent systems. Its most damaging failures involved silent degradation rather than hard crashes, with task completion dropping sharply. That result exposes a limitation of evaluations focused only on apparent capability. An agent can continue operating without making the failure visible to the person relying on it.
MCP-Injector, introduced in October 2026, targets the Model Context Protocol tool-call path with protocol-aware fault injection. Its experiment crossed two backbone sizes, 20B and 120B, and three agent stacks. Faults caused task-completion scores to fall sharply. Larger models did not provide greater fault tolerance, so increased model size was not a substitute for testing behavior under faults.
These findings make fault injection a necessary complement to capability benchmarks. For agents acting on stateful APIs, evaluation also needs to establish that the intended resource changes occurred and that forbidden transitions were rejected. Continuous provider verification keeps that testing environment in step with the system the agent will face. Without it, behavior learned or evaluated against a stationary simulation may fail when the production API changes.
Choosing the right tool at each layer of the test suite
Tool selection should follow the claim a test needs to establish. Stateless mocks are appropriate for a single function in isolation, including assertions about HTTP headers and request body shape. They also suit a dependency with no public specification and no state to track. These tests answer a narrow but useful question about local behavior. They do not need to reproduce a resource lifecycle.
Stateful simulators belong where correctness depends on earlier calls. That includes multi-step flows, webhook handlers triggered by state transitions, and idempotency tests that send the same request twice and assert that the second call creates no duplicate. They also provide the layer for integration tests in CI without live credentials or rate-limit exposure. For those uses, the chosen tool must have cumulative state and continuous provider verification.
Vendor sandboxes have a different role in the final checks. Stripe test mode, for example, supports vendor-specific business logic such as card numbers that trigger particular decline codes, as well as platform-specific edge cases that no third-party simulator replicates. That coverage complements isolated CI testing. The decision is therefore not whether mocks are universally good or bad, but whether the chosen environment can prove the property being tested. When that property depends on what the API remembers, the test environment must remember it too.